India’s AI Benchmarks Need to Leave the Exam Hall
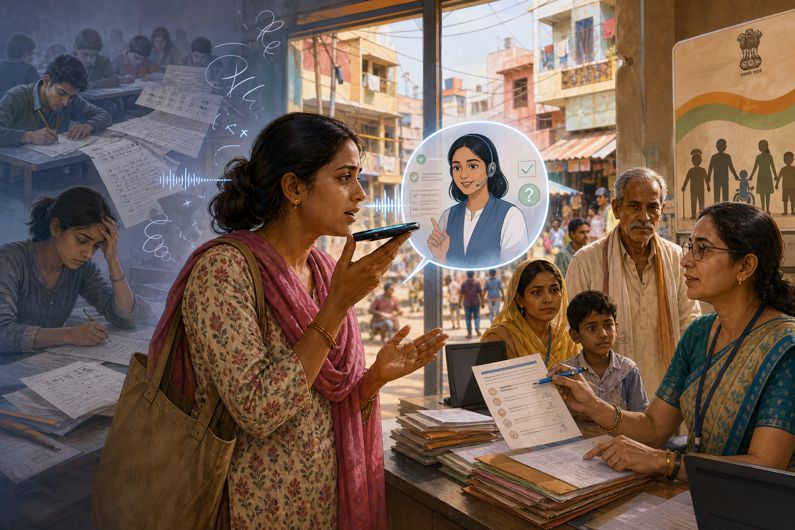
An AI model can answer a difficult exam question and still struggle to help someone understand a government notice. Those are different abilities, yet public discussion often treats a strong benchmark score as evidence that a system is ready for almost any job.
For AI used in Indian public services, I would rather see a less glamorous test: can a person ask an imperfect question, in the language they actually speak, and receive useful guidance without being misled?
That means testing more than translation. A question might mix Hindi and English, use a local name for a scheme, or arrive as a voice message recorded beside traffic. The system must work out what is being asked without quietly inventing the missing details.
Fluent answers can hide practical failures
Consider a hypothetical assistant explaining eligibility for a state benefit. Its answer could be grammatically excellent but based on another state’s rules. It could correctly describe the scheme while missing a recent application deadline. Or it could list documents without distinguishing between mandatory evidence and acceptable alternatives.
None of these failures requires the model to sound confused. That is precisely the problem.
Public service AI evaluation should measure whether people can take the right next step, not simply whether an answer reads well. Depending on the service, that could mean finding the correct application channel, identifying a missing document, or recognising that the available information is insufficient to determine eligibility.
This is not an argument against conventional benchmarks. They help compare capabilities under controlled conditions. But multilingual AI benchmarks and real service evaluations answer different questions. One cannot substitute for the other.
What a more useful test would include
- Ordinary language: Test code-switching in voice interfaces, regional vocabulary, incomplete sentences, and corrections made halfway through a request.
- Local rules: Check whether the assistant distinguishes between jurisdictions and uses current official information, with a visible source and date where relevant.
- Uneven performance: Report results separately for supported languages and input types. A high average can conceal a service that works poorly for a particular group.
- Recovery: Measure whether clarification actually helps, and whether human escalation in public services is available when the system cannot resolve the issue.
These tests should involve intended users, with appropriate consent and privacy protections—not just developers writing prompts they already know the system can handle. AI task completion rates should also be checked against correctness: confidently sending someone through the wrong process is not successful completion.
There is an established basis for this approach. The NIST AI Risk Management Framework treats context, measurement, and ongoing risk management as central to trustworthy deployment. It is a useful reference, not a certification that any particular assistant is safe.
The harder question is whether organisations will publish real-world AI testing results when those results are uneven. They should. A clear statement that a service handles written Marathi more reliably than noisy voice requests is more useful than an unsupported promise of universal access.
For public-facing AI, “we support this language” should be the beginning of the evidence—not the end of it.
Working as Web Developer with Google in Toronto. I have 1 year of experience in web development with React and Node.js. I graduated from George Brown College with a diploma in Computer Programming. In my free time I like photography and cycling.